What Is Retrieval-Augmented Generation? A Technical Marketer’s Guide
The pipeline behind grounded AI answers, and what it means for the content your brand publishes

Rod Stockebrand
Co-founder, Brandleap.ai
Key Takeaways
Short on time? Here are the top things to know.
Article framework
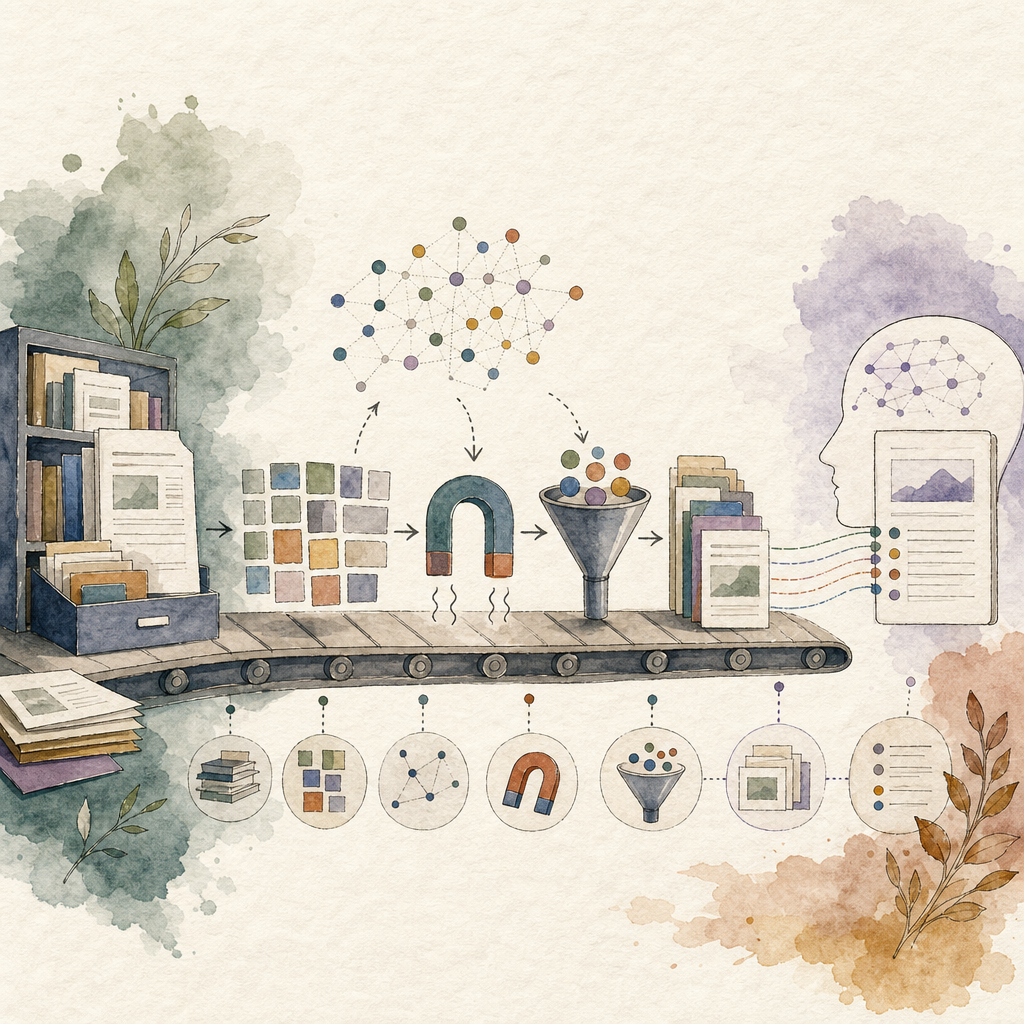
How the key ideas connect
What is retrieval-augmented generation (RAG)?
What are the main stages of a RAG pipeline?
Why does hybrid search matter in RAG?
How should marketers write content for RAG systems?
Does RAG eliminate SEO?
The model is not the library
Ask a language model a question about your product, your latest pricing, or an internal policy and you quickly meet its boundary: its parameters are not a live database of your business. Training data can be old, your private documents were not included, and a fluent answer can still be wrong. A model can write “according to your policy” without having seen your policy at all.
Retrieval-augmented generation (RAG) is the engineering pattern that puts evidence in front of the model at answer time. The system searches a corpus, selects passages, inserts them into a prompt, and asks the model to answer from that context. The original RAG paper, by Lewis and colleagues, describes this as combining a parametric memory (the model) with a non-parametric memory (an external index). The distinction is useful for marketers: your website, docs, and product data become a source the answer system can consult, rather than facts it has to guess.
RAG does not make a model automatically truthful. It gives the model a chance to use relevant evidence. The quality of that evidence, and the system’s discipline about citing it, still determine the answer.
You may have read our HtmlRAG post. This article is the wider map; HtmlRAG is a specific argument about preserving HTML structure during retrieval. The same principle appears here: every transformation between your page and the model can preserve meaning or quietly destroy it.
First, build the corpus
RAG starts before search. An ingestion job collects the materials the system is allowed to use: web pages, help-center articles, PDFs, release notes, support tickets, database records, or a content-management-system feed. It extracts text and useful metadata, then writes records to an index. This is not a one-time upload. A sensible pipeline detects updates, removes withdrawn versions, preserves source URLs, and records when a document was fetched or published.
Extraction is where many “AI” projects become ordinary data engineering. A PDF parser may separate a heading from the paragraph beneath it. A table-to-text conversion may scramble a row and its value. A JavaScript-rendered page may arrive empty to a crawler. Keep the source identifier, title, heading path, canonical URL, language, access permissions, publication date, and content version alongside the text. Metadata supports filters, freshness rules, debugging, and citations later.
- Ingest only sources the product is permitted to retrieve and show.
- Preserve heading hierarchy, lists, tables, links, and code where they carry meaning.
- Attach provenance: URL or document ID, title, author, date, and version.
- Make updates and deletions idempotent so an old claim does not linger in the index.
- Log extraction failures instead of silently indexing an empty or partial document.
Chunking is an editorial decision wearing a technical label
A language model usually cannot receive an entire knowledge base in one prompt, so the ingested material is split into chunks. A chunk that is too small loses qualifiers: “available in Europe” may be separated from the product it qualifies. A chunk that is too large contains several topics and makes retrieval less precise. There is no universal best chunk size. The right boundary follows the content and the question.
Start with document structure. Keep a heading with the paragraphs it governs, retain a table with its header, and avoid splitting a procedure halfway through a numbered sequence. Fixed token windows with overlap are a useful baseline, not a law. Parent-child retrieval is another practical pattern: retrieve a focused child passage, then provide the model with its larger parent section for context. Whatever strategy you choose, store the heading path and chunk position so a retrieved excerpt can be understood and cited.
A chunking choice in practice
✗ Un-optimized
“The Pro plan costs $49 per month.” [next chunk] “Annual billing includes two months free for teams of up to 20.”
✓ Triple-rich rewrite
“Pricing — Pro plan: $49 per month. Annual billing includes two months free for teams of up to 20.”
The second chunk is not more persuasive. It is more retrievable. It carries the product, price, billing condition, and audience together, so an answer engine does not have to reconstruct the fact from neighboring fragments.
Embeddings turn meaning into a search signal
An embedding model maps text to a vector: a list of numbers that represents patterns in meaning. The system embeds every chunk during indexing and embeds the user’s query at runtime. A vector database or vector-enabled search engine then finds chunks whose vectors are close according to a similarity measure. This is why a search for “cancel my subscription” can find a passage titled “Ending your plan,” even when the words do not match exactly.
Embeddings are not a semantic truth machine. They can blur precise distinctions, struggle with very short or highly specialised strings, and reflect the model’s language and domain coverage. Embed the same way at indexing and query time, test the model on your vocabulary, and keep the original text available. A vector is an index signal; it is not a substitute for reading the source.
Why good systems search two ways
Lexical search, such as BM25, scores overlap between query terms and document terms. It is excellent for exact names, SKUs, error codes, legal phrases, and uncommon product terminology. Dense vector search captures paraphrase and conceptual similarity. “How do I stop renewal?” can retrieve “turn off automatic billing” even without shared wording.
Hybrid search combines the rankings or scores from both methods. A common implementation retrieves candidates from each and fuses their rankings, then deduplicates by document or passage. The point is not that one method is old and the other is clever. They fail differently. Exact matching protects identifiers; semantic matching protects intent. Measure both on the questions your customers actually ask.
Reranking spends compute where it matters
Initial retrieval is designed for speed and recall. It might return dozens of candidates, including passages that are broadly related but not the best answer. A reranker then examines the query and each candidate together and produces a more targeted relevance order. Cross-encoders are a familiar example: unlike a bi-encoder that embeds the query and passage separately, a cross-encoder can attend to their interaction while scoring the pair.
Reranking is not free, so use it after a wide first pass and before context assembly. Then apply practical filters: permission, locale, product version, document freshness, and source type. A highly relevant document the user is not allowed to see is not a good result. Neither is a 2022 price page when a current pricing page exists.
Context assembly is where the answer is framed
The top-ranked passages are assembled into the model’s context with instructions. Ordering matters. Put the question in clear language, label each source, include enough surrounding text to preserve qualifiers, and avoid repeating the same passage until it crowds out diversity. A context budget is not an invitation to paste everything retrieved. More text can mean more distractors and more opportunities for conflicting claims.
Question: Which plans include SSO?

Source [1]
Title: Security features
URL: https://example.com/security
Passage: SSO is included in the Business and Enterprise plans...

Source [2]
Title: Pricing
URL: https://example.com/pricing
Passage: The Business plan includes SAML SSO; Enterprise includes SAML and SCIM...

Instruction: Answer only from the sources. If the sources do not establish
the answer, say that the evidence is insufficient. Cite the supporting source.
The prompt cannot repair missing evidence. If two sources conflict, the system needs a policy: prefer the latest version, prefer an approved source, or surface the conflict. “Helpful” guessing is precisely what a grounded system is meant to reduce.
Generation and citations are separate jobs
The generator turns the assembled context into prose, bullets, a refusal, or a structured response. It may paraphrase, synthesise multiple passages, and adapt tone. That flexibility is valuable, but it introduces a new failure mode: a response can sound grounded while adding a claim absent from the retrieved text. Tell the model what to do when evidence is missing, and enforce a citation format that maps each claim to a source passage.
A URL at the bottom is not automatically a useful citation. The reader should be able to tell which source supports which statement, and the source should be stable enough to inspect. For web content, keep canonical URLs and descriptive titles in metadata. For internal content, expose a document name, section, and access-controlled link. Citation presence is a feature to test, not a decorative afterthought.
Evaluate retrieval before blaming the model
Evaluation needs a small, representative question set with known relevant sources and an expected answer or rubric. Test retrieval independently: did the relevant passage appear in the top k results? Recall@k and related retrieval measures answer that question. Test generation separately: is the answer supported by the context, does it answer the question, is it complete, and are citations correctly attached? A beautiful answer cannot rescue a retriever that never found the pricing page.
- Retrieval: recall of the relevant passage, ranking quality, duplicate rate, and filter correctness.
- Groundedness: every material claim is entailed by the supplied context.
- Answer quality: correctness, completeness, relevance, and appropriate uncertainty.
- Citations: the cited passage actually supports the claim and the link resolves for its audience.
- Operations: latency, token use, index freshness, failure rates, and regressions after content changes.
Build a “hard questions” set, not a demo set: ambiguous product names, current prices, negations, version differences, tables, and questions whose answer is “we do not publish that.”
What this changes for web content teams
Your page is no longer consumed only as a page. It may be crawled, extracted, chunked, embedded, retrieved as one passage, and quoted without your navigation or visual hierarchy. That makes the old content fundamentals more technical, not less important. Put a direct definition near the top. Use descriptive headings. Name the product or organisation rather than relying on “we” in every sentence. Keep a claim and its conditions together. Publish the effective date when time matters.
Write for extraction without writing like a database. A clean answer-first paragraph can still have a human voice after it. Tables should have explicit headers; images should not be the sole home of a price or specification; client-side rendering should not hide the only version of an FAQ. Stable canonical URLs and clear revision signals help both conventional crawlers and retrieval pipelines find the right source.
This is where RAG and SEO meet, but they are not interchangeable. SEO helps a page be discovered, crawled, understood, and visited. RAG determines whether a system retrieves some representation of that content for a particular question and how it uses the evidence. Improve the source instead of trying to “optimise for a vector” in isolation. Measure whether your important facts are retrievable, current, and cited.
Your practical audit
Choose ten real questions from sales calls, support tickets, and site search. For each, identify the page that should answer it. Copy the answer-bearing section into a plain document and ask whether it still makes sense without the hero, tabs, chart, or preceding five paragraphs. Then inspect the implementation: does ingestion preserve the section, does chunking keep the qualifiers, does hybrid retrieval return it, and does the final answer cite it?
That exercise turns RAG from a fashionable acronym into a content diagnostic. If the right page is not retrieved, investigate indexing, terminology, and chunk boundaries. If it is retrieved but not cited, investigate context assembly and generation instructions. If it is cited but wrong, investigate stale versions and conflicting sources. Each failure points to a different fix.
Primary references: Lewis et al., “Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks” (NeurIPS 2020); Karpukhin et al., “Dense Passage Retrieval for Open-Domain Question Answering” (EMNLP 2020); and Robertson and Zaragoza, “The Probabilistic Relevance Framework: BM25 and Beyond” (Foundations and Trends in Information Retrieval, 2009).