What Is Answer Engine Optimization?
A technical guide to retrieval, selection, and citation

Rod Stockebrand
Co-founder, Brandleap.ai
Key Takeaways
Short on time? Here are the top things to know.
Article framework
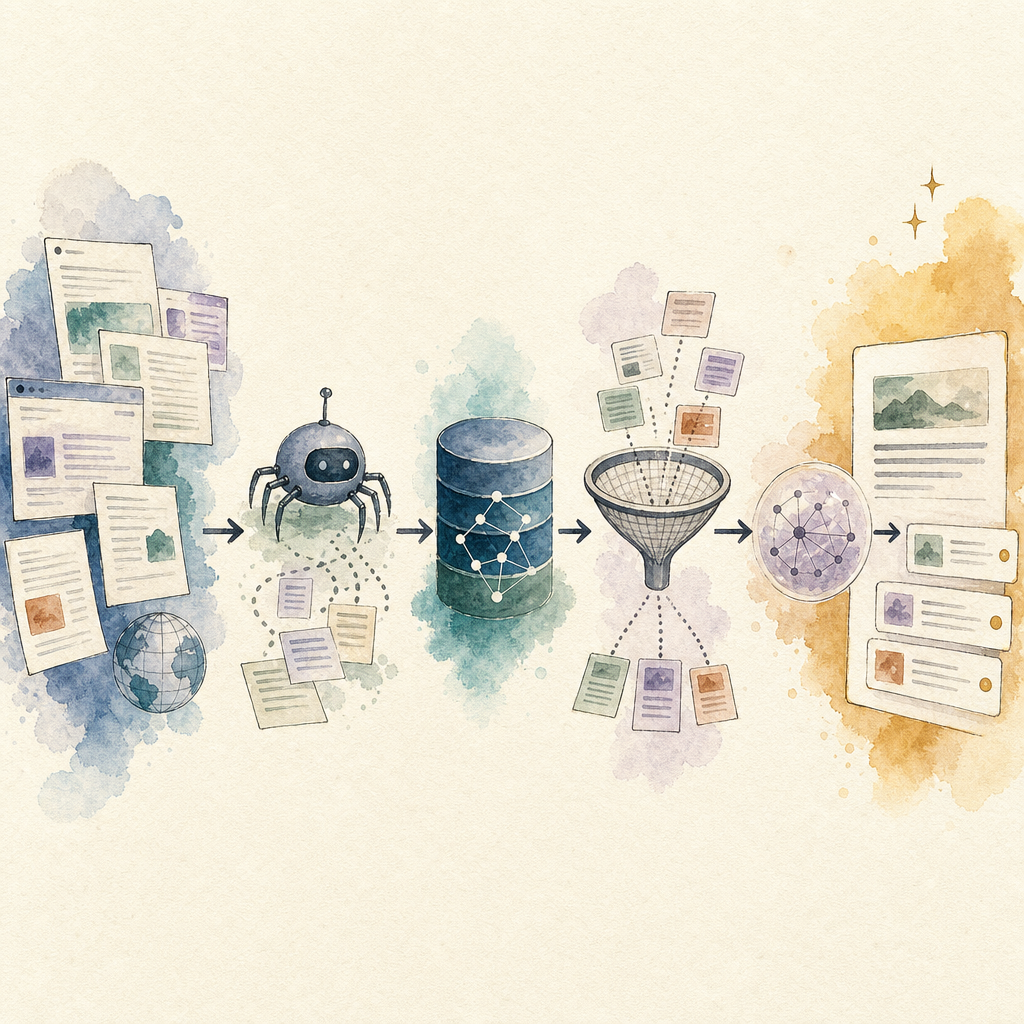
How the key ideas connect
What is Answer Engine Optimization (AEO)?
How does an answer engine produce an answer?
What makes a page easy to retrieve and select?
How do citations get earned in AI answers?
How should a team measure AEO?
The page is no longer the final product
Ask an old-fashioned search engine a question and it gives you a set of destinations. Ask an answer engine and it gives you a constructed response: a paragraph, a comparison, a list of steps, sometimes a set of links or citations. The difference is not cosmetic. The system has to decide which pieces of the web are relevant, which claims are useful, and which sources deserve to appear beside the answer.
That is the job Answer Engine Optimization (AEO) is trying to address. My definition is deliberately unglamorous: AEO is the practice of making a brand’s information retrievable, understandable, selectable, and attributable in systems that answer questions. It is not a replacement for SEO. Search fundamentals still determine whether a page can be crawled, rendered, indexed, and found. AEO adds a second question: when the system has to compose an answer from many sources, is your evidence shaped well enough to make the cut?
AEO is an optimization problem at the evidence layer. You are not optimizing for a single “AI ranking”; you are improving the odds that accurate, useful facts about your entity are found and cited across changing retrieval systems.
Start with the pipeline, not the acronym
There is no single answer-engine architecture. Chat products, search features, enterprise assistants, and shopping agents use different indexes, models, retrieval policies, and citation interfaces. Still, a retrieval-augmented generation (RAG) pipeline gives us a practical map. The original RAG research described a model that combines parametric knowledge in its language model with non-parametric knowledge retrieved from an external index. Modern products add their own routing, safety, ranking, and presentation layers.
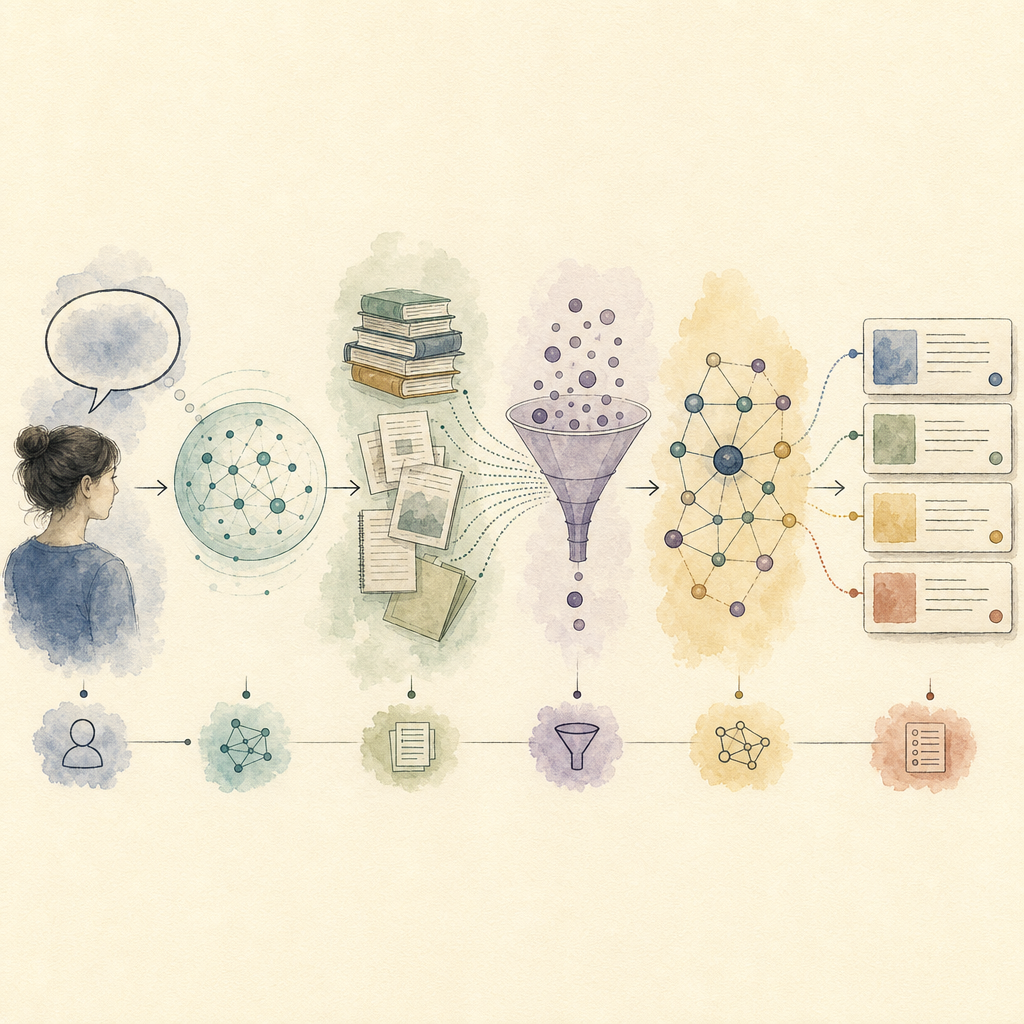
- Interpretation and routing: classify the question, identify entities and constraints, and decide whether external search or a specialized source is needed.
- Retrieval: create one or more searches or vector queries and fetch candidate documents, passages, products, or records.
- Selection: rank, deduplicate, filter, and sometimes rerank candidates for relevance, quality, freshness, and coverage.
- Synthesis: provide selected context to a language model or another generator, which composes an answer under product and safety instructions.
- Citation: map claims or answer segments back to supporting sources when the product exposes citations.
- Feedback: learn from clicks, corrections, evaluations, freshness signals, and subsequent queries.
The important implementation detail is that a page can fail at any stage. A beautifully written article that is blocked from crawling cannot be retrieved. A crawlable page with vague language may be retrieved but lose at selection. A well-supported passage can be selected yet not cited if the product does not expose citations or cannot map the generated claim to the passage. Diagnose the stage before changing the copy.
Stage one: become retrievable
Retrieval starts with availability, not clever wording. Google’s documentation for AI features says the same foundational SEO practices apply: pages need to meet technical requirements for crawling and indexing, and there is no special AI Overview markup that guarantees inclusion. That is a useful antidote to the AEO gadget market.
Audit the boring surfaces first. Make sure important content is present in the delivered HTML or otherwise accessible to the relevant crawler. Check robots.txt, noindex directives, canonical URLs, status codes, internal links, sitemap coverage, and mobile rendering. Do not hide your product’s price, compatibility, clinical indication, or service area solely behind a client-side interaction. A human can click a tab; a retrieval system may receive a blank container, a stale cache, or a version without the answer.
Then improve document signals. Give each page a precise title, a useful description, one descriptive main heading, and a heading hierarchy that reflects the subject. Put the entity name and the answerable topic in the same vicinity. A page titled “Solutions” gives a retriever much less to work with than “Webhook delivery for multi-tenant SaaS applications.” This is not keyword stuffing. It is labeling the document the way you would label a record in a database.
Stage two: make passages selectable
Retrieval is usually passage-shaped. Even when a system initially finds a URL, a later step may split the document into chunks, score those chunks, or ask a reranker to compare them with the question. Your design target is therefore not only “a good page”; it is a passage that still answers the question after it has been lifted out of the page.
The same claim, two retrieval surfaces
✗ Un-optimized
“Our platform helps modern teams work smarter with secure, seamless automation. Explore the possibilities.”
✓ Triple-rich rewrite
“TaskForge is project-management software for engineering teams of 10–200 people. Its Pro plan includes sprint planning, GitHub integration, and audit logs.”
The second version names the subject, category, audience, plan, and capabilities. A retriever can match “project-management software for engineering teams” or “does TaskForge integrate with GitHub” to explicit tokens and relationships. A reader can also quote it without reconstructing who “we” means.
Write each important section in this order: direct answer, qualification, evidence, then detail. State dates, units, scope, geography, version, and source where they matter. Tables are useful for relationships, but repeat critical values in accessible text and label the row and column context. Replace “the option above” with the product name and action. Replace “we serve the region” with the actual locations. These small edits make content more portable when a system takes one paragraph and leaves the navigation, chart, and neighboring caveat behind.
Stage three: give the selector reasons to trust you
Relevance is necessary but not sufficient. A selection layer may consider authority, originality, freshness, geographic fit, first-hand experience, and whether multiple sources agree. We should be precise here: vendors rarely publish the complete scoring function of their answer systems, so anyone presenting a universal “citation score” is selling a guess.
You can improve the evidence a system sees. Put the publication or update date next to claims that change. Identify the author and their expertise. Link original research, standards, primary documentation, or a transparent methodology. Separate observed results from recommendations. If you report a number, include its denominator, time period, population, and source. If a claim is yours rather than independently verified, say so. A precise limitation is a trust signal, not an apology.
Entity consistency matters too. Use one canonical name, connect the organization to its official profiles, and keep address, ownership, product names, and service descriptions consistent across the site and reputable third-party references. Schema.org JSON-LD can express these relationships in a machine-readable form. It does not force an engine to use your facts, and it must not describe content that users cannot see. Treat markup as a synchronized index card, not a hidden sales pitch.
{
  "@context": "https://schema.org",
  "@type": "SoftwareApplication",
  "name": "TaskForge",
  "applicationCategory": "ProjectManagementApplication",
  "description": "Project-management software for engineering teams.",
  "offers": {
    "@type": "Offer",
    "price": "12",
    "priceCurrency": "USD",
    "priceValidUntil": "2026-12-31"
  }
}
That snippet is useful only if the visible page supports it and the price is maintained. Google’s structured-data guidance is clear that markup helps systems understand page content; it is not a guarantee of a search feature. Validate it, monitor it, and establish an owner for expiring facts.
Stage four: make citation easy, not theatrical
A citation is a provenance link between an answer and evidence. It is not the same as being mentioned, and it is not proof that every sentence in an answer came from the linked page. Systems can cite a page for one claim while generating adjacent context from other sources or the model’s prior knowledge. Read citations as an attribution interface with limitations.
The practical move is to create claim-to-source alignment. Put the claim in a self-contained passage, name the source in the passage or link it directly, and avoid bundling five unrelated assertions under one citation. Use descriptive anchor text. Keep the canonical source accessible, stable, and current. For research or statistics, publish the methodology and the data’s date. For product facts, maintain one authoritative page and link documentation to it.
Do not manufacture citations, seed fake reviews, or write copy that implies independent validation you do not have. A citation-shaped page with weak evidence may win a short-term extraction and lose the long-term trust signal that matters more.
A technical AEO workflow you can ship
- Inventory questions: collect sales calls, support tickets, site searches, and comparison questions. Rewrite each as the exact question a buyer would ask an assistant.
- Map evidence: for every question, record the canonical URL, answer passage, owner, last verified date, and primary source. Mark gaps instead of filling them with marketing adjectives.
- Fix rendering and crawlability: test the page as delivered HTML, inspect indexation, and make prices, specifications, FAQs, and policies available without requiring a visual interaction.
- Refactor for extraction: lead with a direct answer, name the subject in every standalone passage, define scope, and keep caveats beside the claim they qualify.
- Add and validate structured data: choose only applicable Schema.org types, keep JSON-LD consistent with visible content, and monitor errors after deployments.
- Run answer evaluations: use a fixed prompt set and record presence, factual accuracy, citation URLs, competitor mentions, and answer drift. Save the date and product version.
- Feed findings back to owners: a missing citation may require better documentation, a stale answer may require content operations, and an absent brand may require a crawl or entity fix. Copy is only one lever.
What AEO cannot promise
No ethical practitioner can promise a citation for every prompt. Answer systems change their indexes, models, policies, and interfaces. They may intentionally omit a source, answer from a private corpus, personalize results, or decline a question. Search engines can also show AI features without sending a click, so visibility and traffic are related measurements, not interchangeable ones.
The durable objective is narrower and more useful: when a system needs a fact in your category, make the accurate version easy to discover, verify, and attribute. That work improves human usability and conventional search quality as well. If you find yourself adding invisible keyword blocks, inventing statistics, or promising that one file will “control” an AI model, stop. You have left engineering and entered superstition.
Your first test
Choose ten questions that influence revenue. For each one, ask the answer products your audience actually uses. Save the complete response and citations, then classify the result: correct and cited, correct but uncited, wrong, competitor only, or no useful answer. Now inspect the winning source. Was its claim more specific? Was its page easier to crawl? Did it provide a first-party document, a date, a clear definition, or a better explanation of scope?
Fix one failure at its actual stage and rerun the same questions after a documented interval. That small evaluation set will teach you more than a dashboard that reports a mysterious “AI visibility” percentage. AEO becomes real when it is treated as a content-and-systems feedback loop: retrieval evidence in, answer quality out, corrections back into the source.
Primary references: Google Search Central documentation on AI features and structured data; Lewis et al., “Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks” (NeurIPS 2020); and the NIST AI Risk Management Framework 1.0.